Chapter 8
What Is an AI Agent?
The word behind a trillion dollars of hype fits in one sentence. This chapter gives you the sentence, the loop behind it, and a front-row seat as an agent books Mom's birthday dinner — wrong turns included.
The one-sentence answer
Here is the entire definition, up front, in the framing Anthropic (the maker of Claude) uses:
Key idea
An agent is an LLM using tools in a loop — acting, reading the results of its actions as feedback from its environment, and deciding for itself what to do next, over and over, until the goal is reached. You give it autonomy over how to get there; you keep authority over whether it counts as done.
That's it. No new kind of brain, no secret architecture, no robot body. If you understood the last chapter — an LLM writing tool orders that a harness executes — you already understand 90% of agents. The remaining 10% is one word: loop.
In Chapter 7, you drove. You asked for the weather; the model made one tool call; you read the result and decided what to ask next. An agent simply moves that "decide what to do next" job from you to the model, and repeats. Treat the agent as a black box for a moment: goal goes in, finished work comes out, and inside there is nothing but the same orange box you already know, running in a circle.
The loop, in four steps
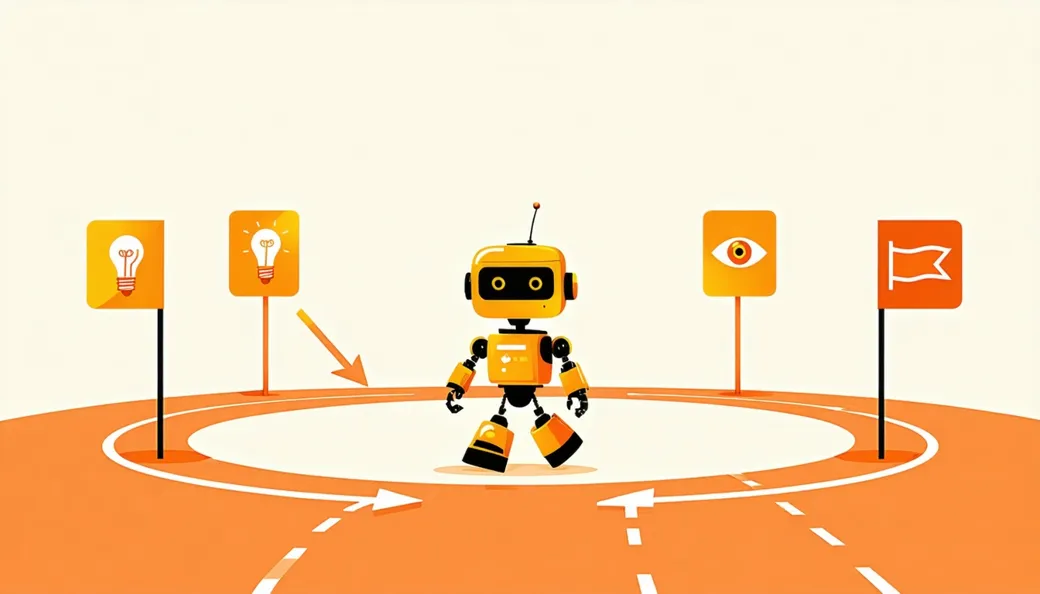
- Goal. A human states what "done" looks like: "Book a birthday dinner for Mom on Saturday. She wants Thai, cozy, under $200 for four."
- The LLM decides the next action. Reading everything in its context — the goal plus every result so far — it picks one step, expressed as a tool request: "First I should
search_restaurants("Thai", near="home")." - A tool executes it. The harness runs the request for real, exactly as in Chapter 7, and gets an actual result.
- The result comes back as feedback. It's pasted into the context, and the model — now knowing more than it did — returns to step 2. The loop repeats until the model declares the goal met, hits a stop condition, or a human calls it off.
Simplified!
"The LLM decides" makes it sound like the model has goals and willpower. It doesn't — each pass through step 2 is the same next-word prediction from Chapter 4. The model is completing the pattern "given this goal and these results so far, a sensible next step would be…" — a pattern it absorbed from training and fine-tuning. The loop behaves like deciding, which is why the shorthand is fine — as long as you remember there's no little planner inside, just prediction pointed at a goal.
Watch it book the dinner
Here's the running example, end-to-end, as a trace — the actual step-by-step log an agent harness would show you. (Real products like Claude Code display almost exactly this kind of narration.)
| # | Agent's reasoning (LLM) | Action & result (tools / world) |
|---|---|---|
| 0 | Goal received: "Book a birthday dinner for Mom on Saturday — Thai, cozy, under $200 for four." | — |
| 1 | "I need candidates first." | search_restaurants("Thai", near="home") → Baan Siam, Thai Orchid, Lemongrass House |
| 2 | "Which are cozy and in budget? Check reviews." | get_reviews("Thai Orchid") → ⚠ "Permanently closed as of March 2026" |
| 3 | Wrong turn caught: "Thai Orchid is closed — my search result was stale. Dropping it; verifying the other two are open." | get_reviews("Baan Siam") → open; 4.6★; "quiet, candle-lit back room"; ~$40/person |
| 4 | "Baan Siam fits: cozy, ≈$160 for four. Now, when on Saturday?" | check_calendar("Saturday") → ⚠ conflict: "Dad's flight lands 6:30pm — home ~7:30pm" |
| 5 | Adapts: "7pm won't work for the whole family. Shift to 8pm." | check_availability("Baan Siam", "Sat 8pm", 4) → table available, back room |
| 6 | "Draft the reservation, but do not book — this is worth a human check." | draft_reservation(...) → Baan Siam, Sat 8:00pm, party of 4, back room, est. $160 |
| 7 | To the human: "I found a cozy Thai spot in budget and drafted an 8pm booking (7pm clashed with Dad's flight). Note: Thai Orchid from my first search turned out to be permanently closed. Confirm and I'll book it." | ⏸ waiting for you |
Read step 3 again, because it's the whole reason agents are exciting. Nobody told the agent Thai Orchid had closed. The environment did — through a tool result — and the model's next prediction incorporated that feedback and rerouted. That self-correction-from-feedback is exactly what a single prompt, however brilliant, can never do: a one-shot answer can't notice that reality disagreed with it.
It's worth pausing to draw the agent's whole world in one picture — the model, its tools, and the one gate where a human stands guard.
Workflows vs. agents — the distinction that cuts through the hype
Here's the vocabulary that separates people who understand this field from people who repeat headlines. Lots of useful LLM systems are not agents — they're workflows: sequences where a developer decided the steps in advance, with LLM calls embedded inside. A workflow for our dinner might be hard-wired: always search → always summarize the top 3 → always email you the list. Every run walks the same path. An agent is different in exactly one way: the LLM itself chooses the steps, at run time, based on what it finds.
| Workflow | Agent | |
|---|---|---|
| Who decides the steps? | A developer, in advance — fixed path | The LLM, at run time — path emerges |
| Behavior | Predictable; same input → same route | Flexible; adapts to what it discovers |
| Cost & speed | Cheap and fast — few, known LLM calls | Slower and costlier — many calls, unknown count |
| Failure style | Fails visibly at a known step | Errors can compound quietly across steps |
| Best for | Well-mapped, repeatable tasks | Open-ended tasks where the path can't be scripted |
| Dinner version | "Always search, summarize top 3, email me" | "Get dinner booked — figure out how" |
If the table feels abstract, try this: a workflow is an assembly line — every station bolted in place, every car passing the same stations in the same order, marvelously efficient at the thing it was built for and useless for anything else. An agent is a trusted personal assistant handed a goal and a credit-card limit: "get Mom's dinner sorted, keep it under $200" — free to choose the route, expected to handle surprises, and constrained by a budget rather than a script. One caution before the analogy runs away with you: a human assistant brings years of judgment and can be embarrassed by failure; an agent brings neither, which is exactly why the credit-card limit — the hard, externally enforced constraint — is doing more safety work in that sentence than the trust is.
Why agents fail: the compounding-error problem
If agents can self-correct, why doesn't everyone let them run wild? Arithmetic. Suppose an agent gets each individual step right 95% of the time — genuinely good. Chain 10 steps, and the odds that every step went right are 0.95 × 0.95 × … ten times over: 0.9510 ≈ 0.60. A 95%-reliable step becomes a 60%-reliable task. At 20 steps you're down to ~36% — worse than a coin flip — and one bad step early (a hallucinated restaurant name, a misread date) contaminates everything built on top of it.
Our 0.95-per-step arithmetic is a hypothetical; researchers have since measured the real thing, and the resulting chart has become the field's favorite way to think about agent progress. A research group called METR asks: how long a task (measured in how many minutes or hours it takes a skilled human) can an agent finish at least half the time? They call it the 50% time horizon, and in early 2025 the numbers looked like this:
This is why real agent systems are wrapped in guardrails, and now you know precisely what each one is for:
- Checkpoints — pause and verify at milestones ("candidates confirmed open — proceed?") so errors get caught before they compound.
- Stop conditions — step or budget limits, so a confused agent can't loop forever burning money.
- Human confirmation for consequential, hard-to-reverse actions — booking, paying, sending, deleting. That's why our agent stopped at step 7 instead of booking. Searching is cheap to get wrong; a reservation under Mom's name is not.
Checkpoints work exactly like a new employee's relationship with their manager. In week one, everything goes past the manager's desk: every email draft, every customer promise. As the employee demonstrates reliability, the sign-offs thin out — first only purchases need approval, then only contracts, until eventually just the genuinely irreversible calls come back for a signature. Agent autonomy is granted the same way: earned in proportion to demonstrated reliability, and always retained for the actions that can't be undone. The analogy has one sharp edge, though — a human employee gets permanently better with experience, while today's agent starts every task with the same fixed skill level, so its "probation" never fully ends; you're tuning trust to a track record, not to growth.
Start simple
The best builders follow a rule that sounds almost anticlimactic: use the simplest thing that works. If one good prompt answers the question, use a prompt. If the steps are known in advance, use a workflow — it's cheaper, faster, and debuggable. Reach for an agent only when the path genuinely can't be scripted — when the task requires discovering, mid-flight, what to do next. "Which Thai dish should I cook for Mom?" needs one prompt, not an agent. Agents trade predictability and cost for flexibility; only pay that price when you need it.
Everything in this chapter compresses into one picture — an autonomy ladder. Each rung hands the model a little more of the "decide what happens next" job; each rung costs more, fails in murkier ways, and should only be climbed when the rung below genuinely can't do the task.
Misconception: "Agents are a new kind of AI model"
No. There is no separate "agent model" that thinks differently from a chatbot. The very same LLM that autocompleted your email is, inside an agent, deciding which tool to call — the difference is entirely in the harness: the loop, the tools, and the permissions wrapped around it. Same engine, new drivetrain. (Model makers do fine-tune models to be better at tool use and multi-step work, but that's better training of the same kind of model — not a new species.) So when a headline says "Company X launches an AI agent," the right question is never "what amazing new brain is this?" but "what tools did they give an LLM, what's the loop, and where are the guardrails?"
Try it now (5 minutes)
Watch a real agent loop with your own eyes. Easiest option: open a chatbot with "deep research" mode (ChatGPT, Gemini, Claude, or Perplexity) and ask something multi-step: "Find three well-reviewed Thai restaurants in [your town] that are open Saturday evening, and compare their prices." Don't skim the final answer — watch the narration: searching… reading… refining the search… That running commentary is steps 2–4 of the loop, live. If you or a friend has a coding agent (Claude Code, Cursor, GitHub Copilot), watch it work once: you'll see it try something, read an error, and change course — step 3 of our dinner trace, happening for real.
The ladder, one rung from the top
Look how far the birthday dinner has come. A rule-following bot (Chapter 1) that shattered on the first unexpected input. A learner (Chapter 2) that could rank restaurants but not converse. An LLM (Chapter 4) that discussed the dinner beautifully and invented half the details. A tool-equipped LLM (Chapter 7) with real menus and real weather — but you steering every step. And now an agent: goal in, feedback-driven loop in the middle, a drafted reservation and a raised eyebrow ("shall I book it?") out. One task, climbing the whole capability ladder of this book.
One agent, one goal, one loop. The obvious next thought — "what if there were several?" — is where we go next: teams of LLMs, the patterns for wiring them together, and a standard plug that lets any agent use any tool. That, plus an honest map of what's real and what's hype in mid-2026.
Where to go next
Three resources, easy to deep:
- Ethan Mollick — One Useful Thing (oneusefulthing.org). His agent posts show non-programmers what today's agents actually do well and where they quietly fail — the "jagged frontier," applied to autonomy.
- Simon Willison's blog (simonwillison.net). Willison popularized the refreshingly blunt definition "An LLM agent runs tools in a loop to achieve a goal" and stress-tests real agents in public, wrong turns and all.
- Anthropic — "Building Effective Agents" (anthropic.com/research/building-effective-agents). The source of this chapter's workflow-vs-agent distinction and the "start simple" principle. Written for engineers, but the prose is clear enough that after this chapter, you can read it.